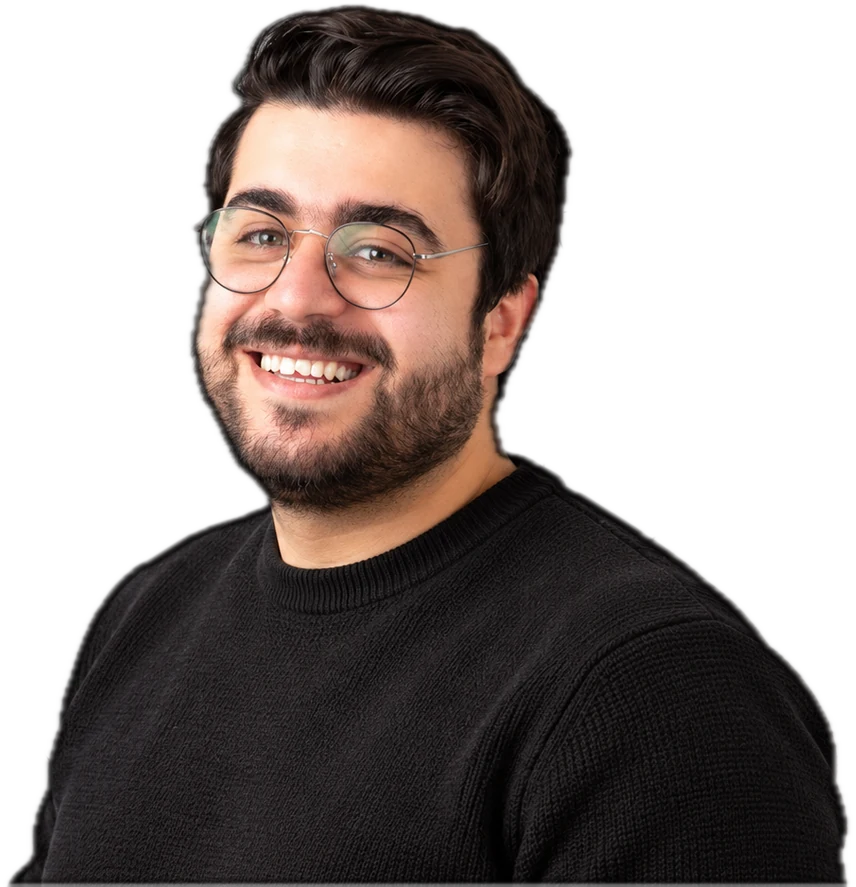
Senior Data EngineerParis, France
I build reliable data platforms, from operational data models to analytics, and turn complex requirements into production systems.
- 5 years of experience across data engineering and BI, from Edelman Intelligence to EY.
- Several billion rows Single-process Python workflows re-architected as distributed PySpark pipelines at Mangabey.
- OLTP to analytics Owning PostgreSQL application models and Snowflake analytical datasets at EY.
- Technical leadership Mentoring junior engineers, co-leading a Data Community of Practice and defining SLA/SLO standards.
(01) Professional experience
From reporting to owning the platform.
Reverse chronological. Select a role to see what I owned, the systems involved and the stack.
-
- Python
- SQL
- PostgreSQL
- Flyway
- Dagster
- dbt
- Snowflake
- Azure
- GCP
- Azure DevOps
- Git
Context
Data engineering inside an Agile delivery setup, working with Scrum and backend/API teams so that data models, interface contracts and dependencies stayed aligned with feature delivery.
What I owned
- Designed PostgreSQL models for OLTP applications, translating business requirements into normalised schemas, relational constraints and indexing strategies.
- Built reusable, object-oriented Python ingestion components for third-party APIs, standardising authentication, pagination and error handling.
- Established data cataloguing and governance practices: metadata, ownership, lineage and data quality standards.
Systems & decisions
- Version-controlled schema migrations with Flyway, delivered through Azure DevOps CI/CD with automated validation, testing and code review.
- Dagster-orchestrated ELT pipelines and dbt models on Snowflake to produce reusable analytical datasets.
- Performance work on both sides: PostgreSQL indexing and SQL tuning, and refined Snowflake transformations and models for efficiency.
Outcomes
A governed, versioned data layer from operational schema to analytical dataset, with standardised API ingestion and defined monitoring SLA/SLO standards.
With the team
- Managed and mentored junior data engineers through code reviews and technical guidance.
- Co-led the Data Community of Practice.
-
- Python
- SQL
- dbt
- Spark / PySpark
- GCP
- Apache Airflow
- Power BI
- GitHub Actions
Context
Data work for pharmaceutical clients on GCP, covering ingestion, transformation and analytics, including datasets of several billion rows.
What I owned
- Designed and delivered end-to-end data architectures on GCP, from ingestion through transformation to analytics.
- Developed SQL transformations and modular dbt models with automated tests and documentation.
- Implemented data quality checks, monitoring and failure alerts.
Systems & decisions
- Migrated single-process Python workflows to distributed PySpark pipelines to improve performance and scalability on multi-billion-row datasets.
- Orchestrated schedules and dependencies with Apache Airflow.
- Automated deployments and environment management with GitHub Actions.
Outcomes
Pipelines built for performance and scalability at several-billion-row volume, with automated testing, documentation and alerting around them.
With the team
- Supervised and mentored a Data Engineer intern and a Data Analyst in the data quality sub-team, coordinating tasks and giving technical guidance.
-
- AWS
- Amazon Redshift
- Python
- SQL
- dbt
- Amazon QuickSight
Context
Large-scale logistics analytics and operational performance reporting for European markets.
What I owned
- Managed and optimised the Amazon Redshift clusters behind logistics reporting.
- Primary contact for delivery and logistics KPIs, aligning reporting requirements and metric definitions with stakeholders.
Systems & decisions
- Automated pipelines and SQL transformations in Python and dbt to deliver business-critical KPIs.
- Developed Amazon QuickSight dashboards for delivery and logistics KPIs.
Outcomes
Business-critical KPIs delivered across European markets, and performance trends and improvement opportunities presented in business reviews with operational teams and leadership.
-
- Google BigQuery
- Python
- SQL
- Power BI
- Excel
Context
Media performance reporting that depended on earned, owned and paid media datasets coming from separate sources.
What I owned
- Built Python and SQL transformation pipelines in BigQuery to centralise and harmonise the media datasets.
- Developed Power BI dashboards and analytical reports to monitor media performance and support business decisions.
Outcomes
Data workflows that improved reporting accuracy, consistency and timely delivery.
(02) Technical expertise
The stack I work with.
-
Languages
Python, SQL
Ingestion, transformation, tuning
-
Databases & migrations
PostgreSQL, MySQL, Flyway
OLTP models, versioned migrations
-
Orchestration & transformation
Dagster, Airflow, dbt, Spark
ELT pipelines, PySpark, tested models
-
Data warehouse
Snowflake, BigQuery
Analytical modelling · SnowPro certified
-
Cloud platforms
Azure, GCP
Platforms and pipelines · AWS earlier
-
Version control & delivery
Git, Azure DevOps
CI/CD, code review
-
Governance & BI
Data cataloguing, lineage, data quality, Power BI
Ownership and metadata standards · dashboards and reports
(03) Certifications & latest reads
Credentials, and what I'm reading.
-
 CertificationSnowPro CoreSnowflake
-
 CertificationSnowPro Advanced: Data EngineerSnowflake
-
Latest readSQL AntipatternsAvoiding the Pitfalls of Database Programming · Bill Karwin
(04) About & engineering approach
I treat operational data and analytics as one system: model it carefully, ship changes safely, and make it trustworthy.
My path runs from BI reporting at Edelman Intelligence and Amazon, through distributed pipelines at Mangabey, to owning both sides at EY: the PostgreSQL models that applications write to, and the Snowflake datasets that analysts read from.
-
Start from the requirement
I translate business requirements into normalised schemas, constraints and indexing strategies, and align data models and interface contracts with backend and API teams.
-
Make change safe
Schema changes ship as version-controlled migrations, with automated validation, tests and code review in the CI/CD pipeline.
-
Build for reuse and trust
Reusable ingestion components and dbt models, plus cataloguing, ownership, lineage and quality standards, so datasets can be relied on.
-
Bring people with me
Code reviews and mentoring for junior engineers, a Data Community of Practice, and shared metric definitions agreed with stakeholders.
Education
- MSc Big Data Analytics IESEG School of Management, Lille · 2021–2022
- BSc Data Analytics & IT Tunis Business School · 2015–2019
(05) CV
My experience, in one document.
Roles, responsibilities, education and certifications, laid out on two pages. Save a copy to keep, or read it in your browser.